ViGLUE A Vietnamese General Language Understanding Benchmark and Analysis of Vietnamese Language Models
Key Findings
94.3
Translation keeps the meaning
Back-translated GLUE sentences have an average semantic similarity of 94.3 to the originals (BLEU 53.5, METEOR 79.4).
7 of 12
XLM-Rlarge is the strongest baseline
It is the best fine-tuned model on seven tasks, including both paraphrase tasks, but it falls to the majority baseline on MNLI and CoLA.
56.34%
WNLI is still unsolved
No fine-tuned model beats the majority-class baseline on WNLI.
k = 0
More examples do not always help
BLOOM and PhoGPT score best with zero-shot prompts on CoLA, MNLI, MRPC, QQP, and WNLI. Only QNLI and VNRTE improve as examples are added.
Twelve Tasks
| Task | Train | Val. | Test | Source | Metric | Domain |
|---|---|---|---|---|---|---|
| Natural language inference | ||||||
| MNLIEntailment, neutral, or contradiction | 392,702 | 9,815 | 9,796 | Translated | Acc. | Miscellaneous |
| QNLIDoes the sentence answer the question? | 104,743 | 5,463 | 5,463 | Translated | Acc. | Wikipedia |
| RTEEntailment or not entailment | 2,490 | 277 | 3,000 | Translated | Acc. | Miscellaneous |
| VNRTEEntailment between Vietnamese news sentences | 12,526 | 3,137 | – | Constructed | Acc. | News |
| WNLIPronoun resolution as entailment | 635 | 71 | 146 | Translated | Acc. | Fiction books |
| Sentiment analysis | ||||||
| SST2Positive or negative movie review | 67,349 | 872 | 1,821 | Translated | Acc. | Movie reviews |
| VSFCSentiment of student feedback (3 classes) | 11,426 | 1,538 | 3,166 | Collected | Acc. | Student feedback |
| VSMECEmotion of social media comments (7 classes) | 5,548 | 686 | 693 | Collected | Acc. | Social media |
| Similarity and paraphrase | ||||||
| MRPCAre two news sentences paraphrases? | 3,668 | 408 | 1,725 | Translated | Acc./F1 | News |
| QQPAre two Quora questions duplicates? | 363,846 | 40,430 | 390,965 | Translated | Acc./F1 | Quora QA |
| Single sentence | ||||||
| CoLAIs the sentence grammatically acceptable? | 8,551 | 1,043 | 1,063 | Translated | MCC | Miscellaneous |
| VToCTopic of a news sentence (15 topics) | 7,293 | 1,831 | – | Constructed | Acc. | News |
MCC: Matthews correlation coefficient. VNRTE and VToC have no test split.
Dataset Preview
Pick a task to browse its training split in the Hugging Face dataset viewer.
from datasets import load_dataset

cola = load_dataset("tmnam20/ViGLUE", "cola")
How ViGLUE Is Built
Translated 8 tasks
Eight GLUE tasks are machine-translated with Google Translate. To check quality, 100 examples per task are translated back to English and compared with the originals by BLEU, METEOR, and semantic similarity.
Constructed 2 tasks
VNRTE and VToC are new corpora built from VnExpress news articles. VToC labels each article's abstract sentence with the article's topic.
Collected 2 tasks
VSFC (student feedback) and VSMEC (social media emotions) are existing Vietnamese datasets, cleaned by removing emoticons and emojis.
VNRTE construction pipeline
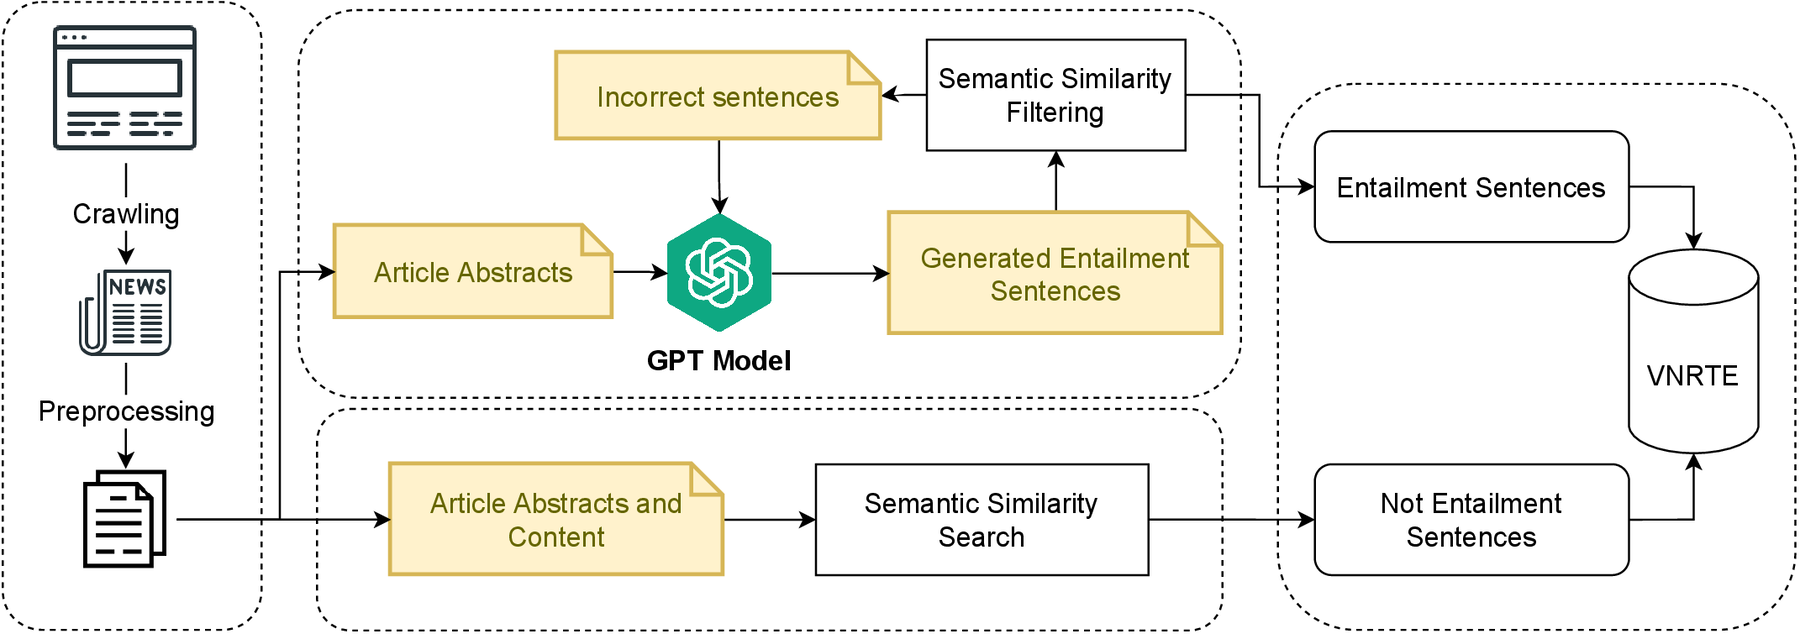
- Entailment: a GPT model rewrites an article's abstract sentence. Pairs with a cosine similarity below 0.9 are rewritten again, for up to four rounds, and then removed.
- Not entailment: a sentence from the same article whose similarity to the abstract is between 0.3 and 0.4, so it is on the same topic but does not follow from it.
Results
Fine-tuned baselines
We fine-tune four multilingual encoders on each task (three seeds each) and report the best validation score. ZeroR always predicts the majority class.
| Inference | Sentiment | Paraphrase | Single sentence | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Model | MNLI | QNLI | RTE | VNRTE | WNLI | SST2 | VSFC | VSMEC | MRPC | QQP | CoLA | VToC |
| Acc. | Acc. | Acc. | Acc. | Acc. | Acc. | Acc. | Acc. | Acc./F1 | Acc./F1 | MCC | Acc. | |
| ZeroR | 35.45 | 50.54 | 52.71 | 53.11 | 56.34 | 50.92 | 50.85 | 31.20 | 68.38/81.22 | 63.38/0.00 | 0.00 | 6.77 |
| mBERT | 79.66 | 89.11 | 70.76 | 99.97 | 56.34 | 88.42 | 93.62 | 53.64 | 85.29/88.85 | 89.12/85.16 | 14.13 | 81.43 |
| XLM-Rbase | 81.61 | 88.17 | 62.45 | 100.00 | 56.34 | 89.45 | 94.95 | 55.25 | 83.82/88.26 | 89.46/85.87 | 3.64 | 83.07 |
| XLM-Rlarge | 35.45 | 91.23 | 67.51 | 100.00 | 54.93 | 90.14 | 95.39 | 37.90 | 88.24/91.64 | 90.48/87.22 | 0.00 | 87.82 |
| mDeBERTaV3 | 83.34 | 89.99 | 69.31 | 99.97 | 56.34 | 89.79 | 95.07 | 55.39 | 86.52/90.05 | 89.98/86.69 | 19.62 | 80.88 |
Validation results × 100; MNLI uses the matched validation set. The best score for each task is in blue. The paper also reports PhoBERT and ViDeBERTa and every seed.
- XLM-Rlarge is best on seven of twelve tasks, and XLM-Rbase never beats it, so a larger model helps on most tasks.
- mDeBERTaV3 is second: it is best on MNLI, VSMEC, and CoLA, and within 1 point of the best model on most other tasks.
- On WNLI, every model scores at or below the majority baseline.
Few-shot prompting of LLMs
We prompt the BLOOM family (560M to 176B) and the Vietnamese PhoGPT-7B5 with k = 0, 1, 2, or 4 examples in the context, without fine-tuning. The paper's appendix also evaluates community Vietnamese LLMs (Vietcuna and Hoa).
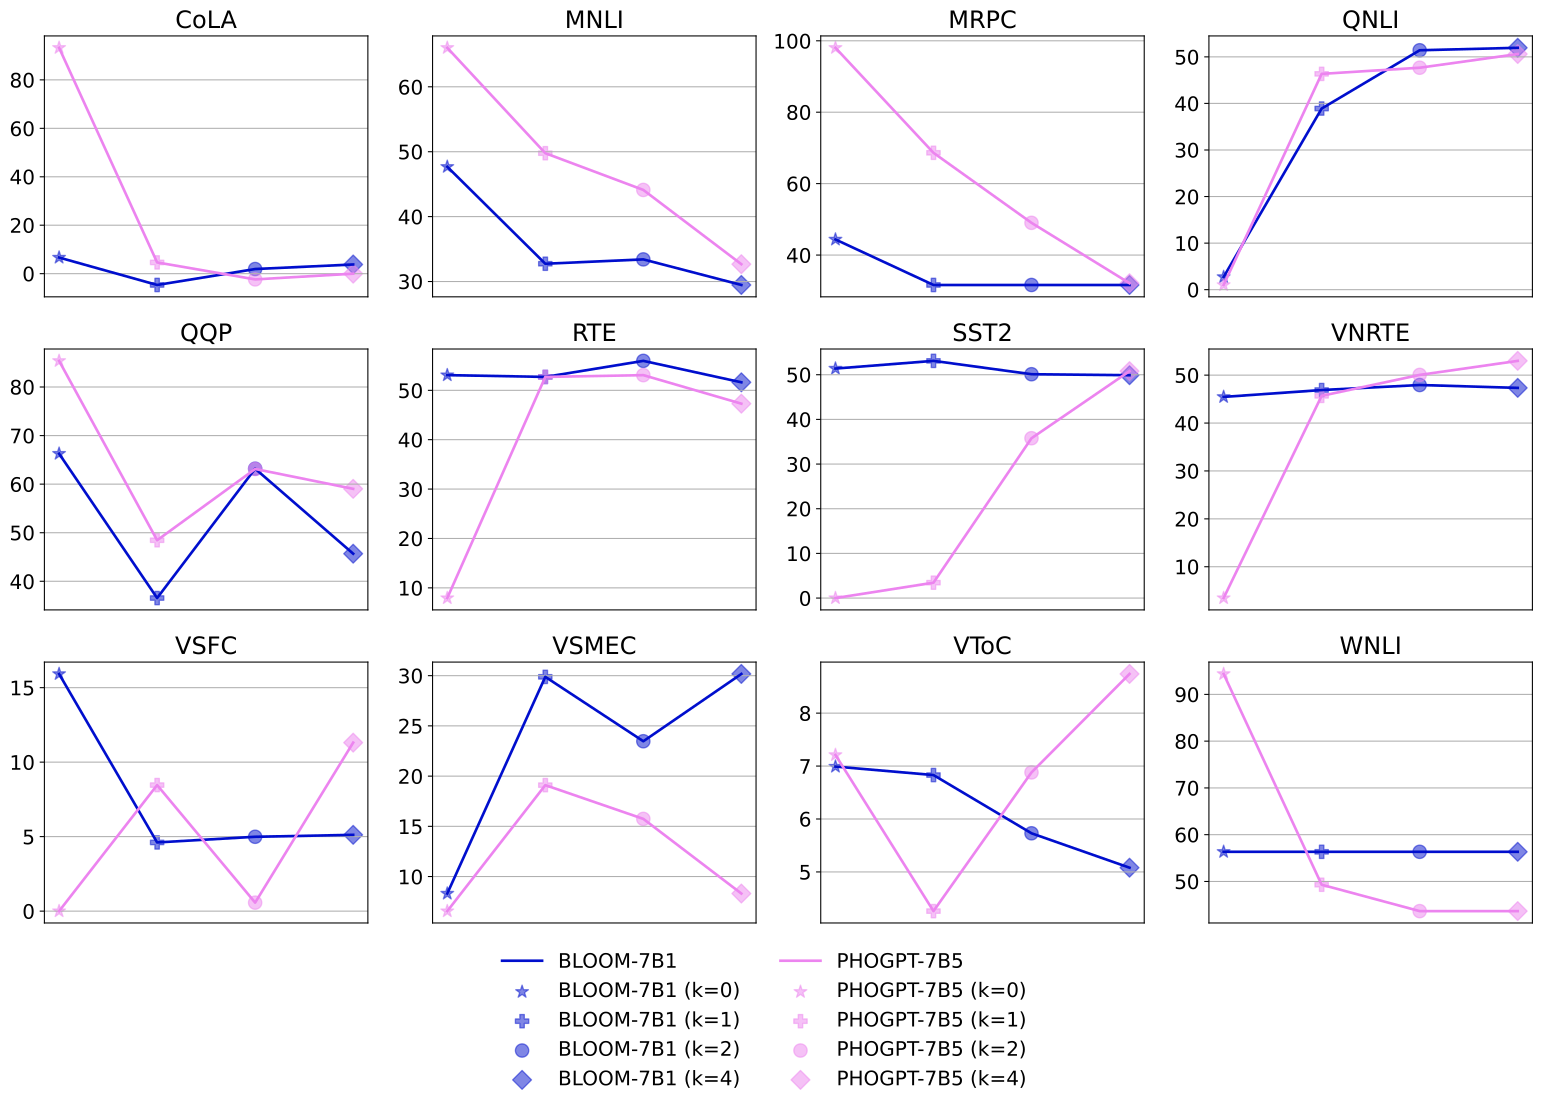
Scores × 100. All tasks use accuracy except CoLA (MCC).
- With zero-shot prompts, PhoGPT beats BLOOM-7B1 on six of twelve tasks. With k = 1, 2, and 4, BLOOM-7B1 wins on five, seven, and five tasks.
- Zero-shot prompts score highest on CoLA, MNLI, MRPC, QQP, and WNLI; more examples help on QNLI and VNRTE.
- On QQP, SST2, VSFC, and VSMEC, scores go up and down as k changes.
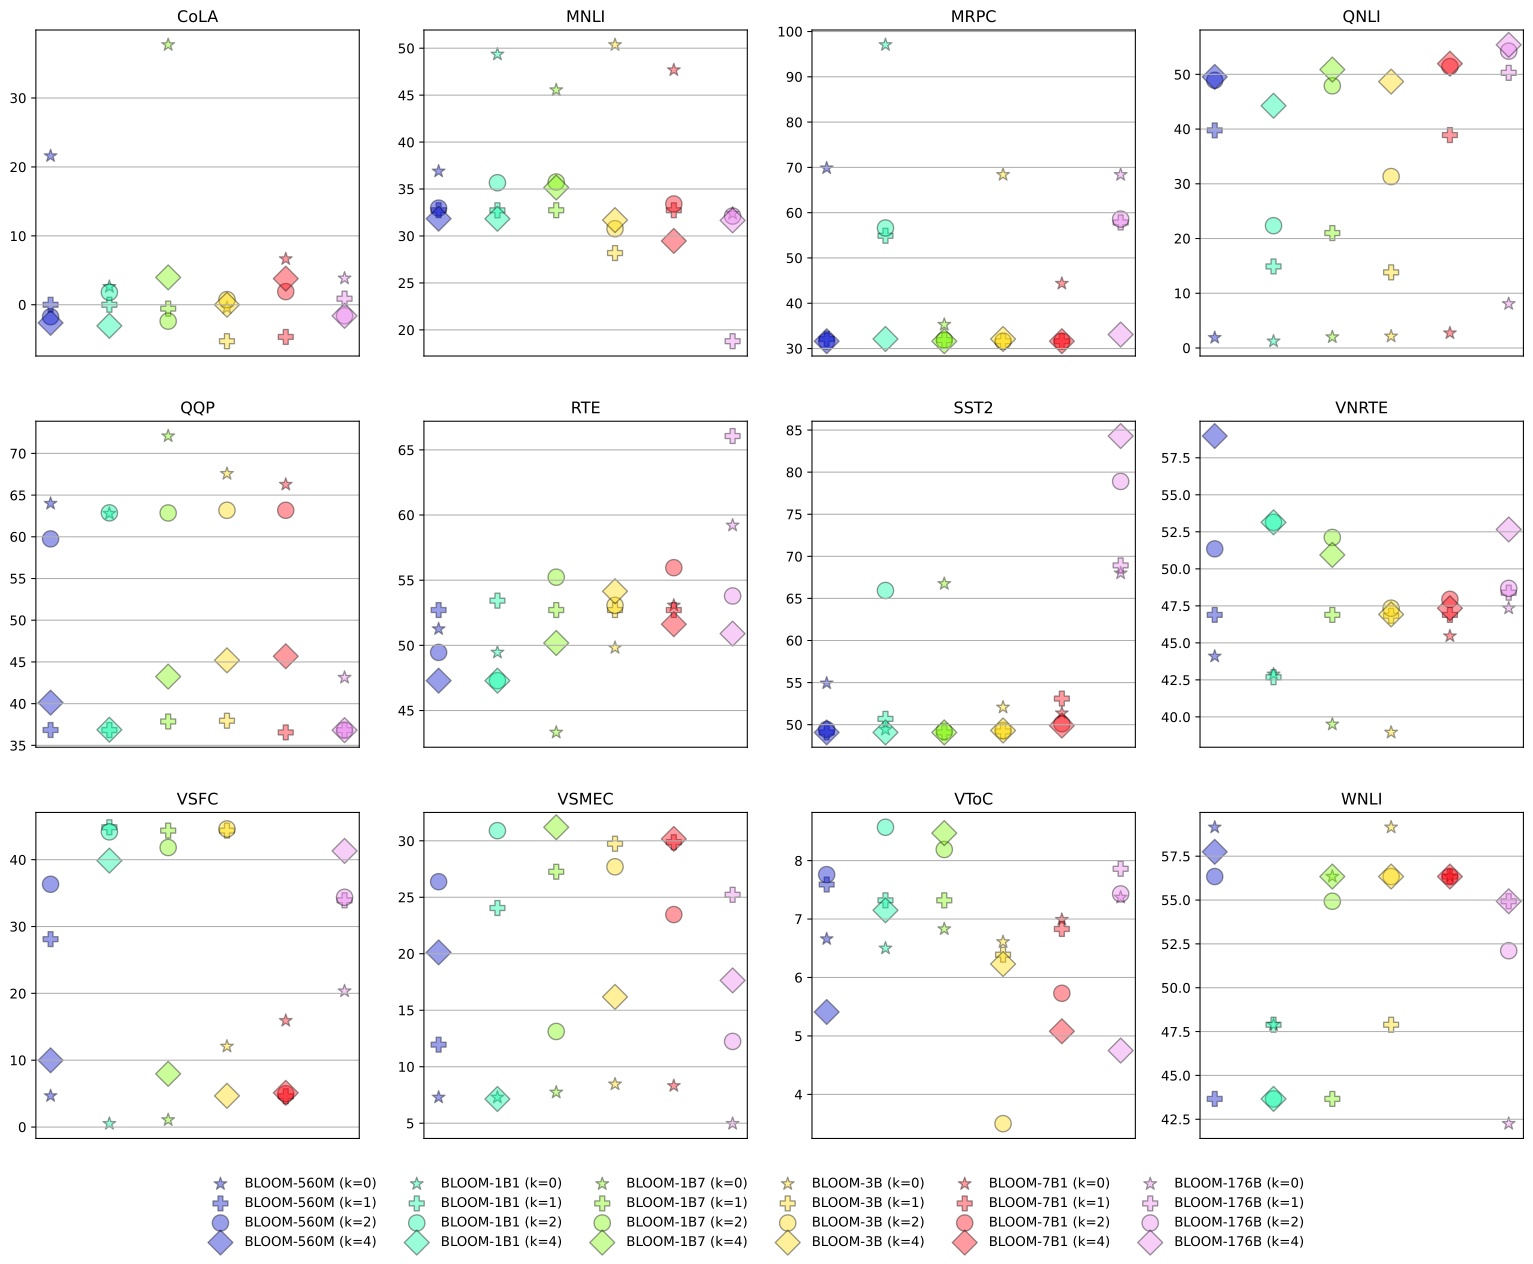
Stars, plus signs, circles, and diamonds mark k = 0, 1, 2, and 4.
- More examples help every BLOOM size on QNLI, while CoLA, MNLI, MRPC, and QQP are always best at k = 0.
- BLOOM-176B beats the smaller models only on QNLI, RTE, and SST2.
- Larger models improve on QNLI, QQP, RTE, SST2, VSFC, and VSMEC, but the smallest model, BLOOM-560M, is best on VNRTE and WNLI.
BibTeX
@inproceedings{tran-etal-2024-viglue,
  title     = {{V}i{GLUE}: A {V}ietnamese General Language Understanding Benchmark and Analysis of {V}ietnamese Language Models},
  author    = {Tran, Minh-Nam and Nguyen, Phu-Vinh and Nguyen, Long and Dinh, Dien},
  editor    = {Duh, Kevin and Gomez, Helena and Bethard, Steven},
  booktitle = {Findings of the {A}ssociation for {C}omputational {L}inguistics: {NAACL} 2024},
  month     = jun,
  year      = {2024},
  address   = {Mexico City, Mexico},
  publisher = {Association for Computational Linguistics},
  url       = {https://aclanthology.org/2024.findings-naacl.261/},
  doi       = {10.18653/v1/2024.findings-naacl.261},
  pages     = {4174--4189}
}